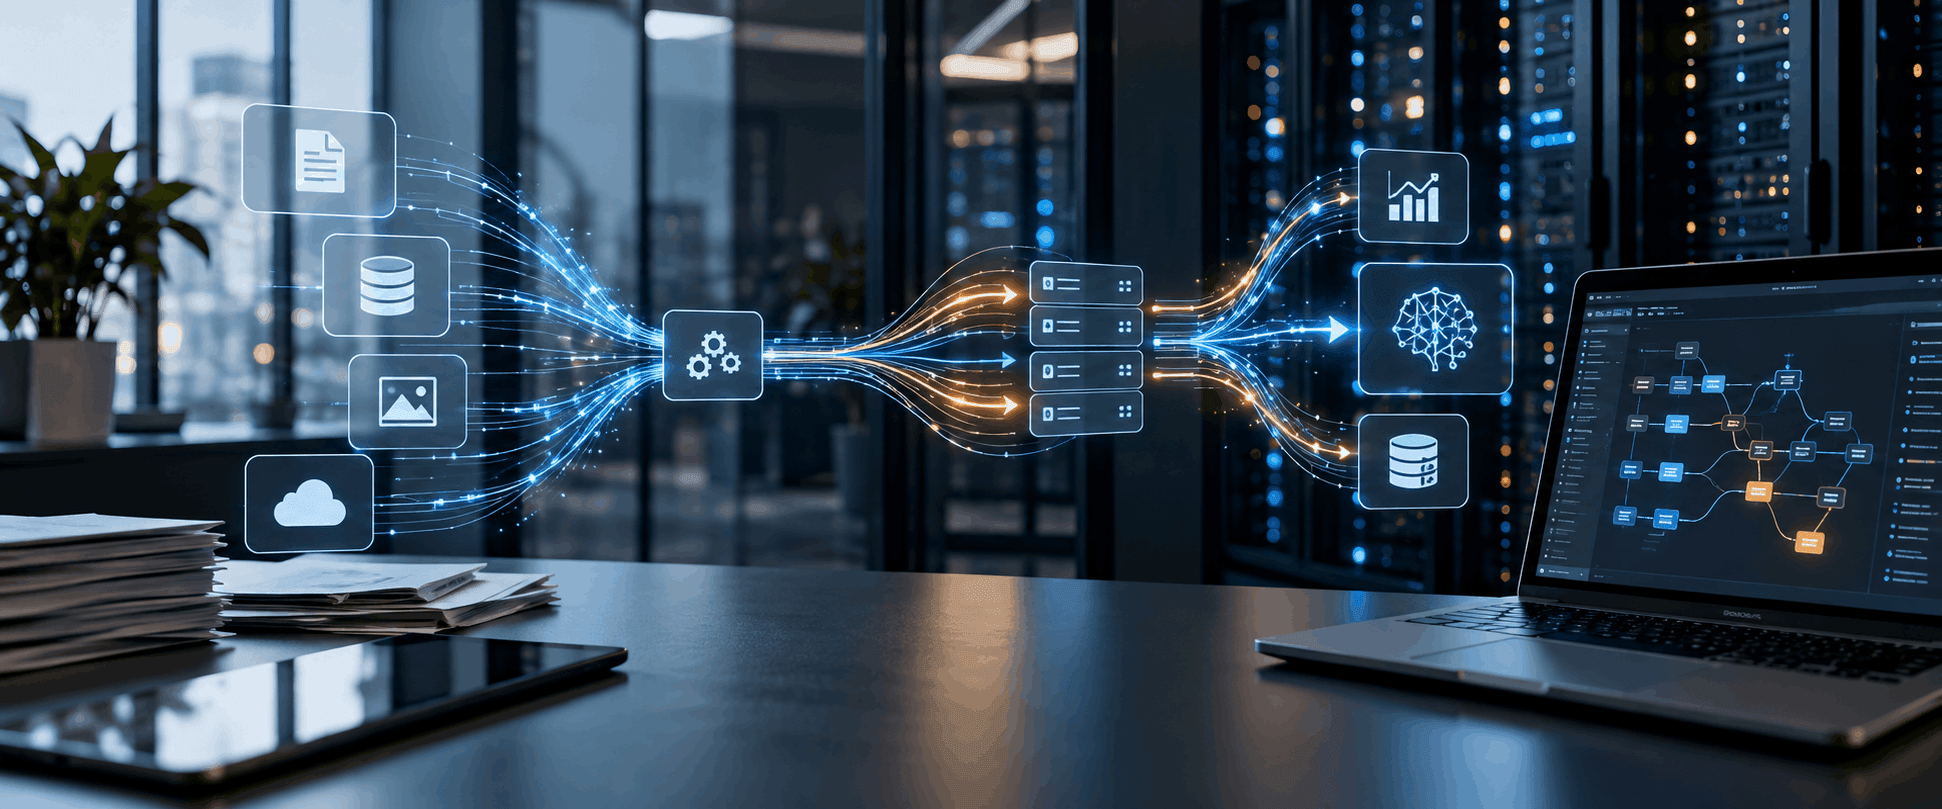
Key Takeaways
You leave this article with a practical answer to the title: enterprises track AI data by drawing the real routes information travels across copilots, APIs, retrieval systems, agents, and logs, then maintaining that map as usage changes. The bullets below are the decision rules security, privacy, and engineering leads use when they stop guessing and start tracing.
- AI data flow mapping is an inventory of paths — sources, transformations, destinations, retention, and owners — not a one-page diagram filed after a pilot.
- Tracking AI data means following prompts, retrieved chunks, tool calls, outputs, and secondary copies in logs and caches, not only the primary model call.
- Shadow AI and embedded product features widen the map; approved tools are only part of the story.
- Mapping without enforcement is documentation; value shows up when privacy controls sit at hops where sensitive data would leave your control.
- Lineage, system inventory, and flow maps overlap but answer different questions — provenance, list of AI systems, and routes data actually travels.
- Regulated teams use maps as audit evidence while still treating technical controls as support for — not a substitute for — legal review.
Keep those points close as you read. The sections that follow show what a usable map looks like, where enterprises miss traffic, how mapping feeds privacy and governance work, and where a privacy-first layer such as Questa AI fits once you know the routes.
What Is AI Data Flow Mapping?
AI data flow mapping is the practice of documenting how information moves whenever people or systems interact with artificial intelligence — which source systems feed a prompt or pipeline, what transformations happen along the way, which models or vendors receive the content, what returns in the response, and where copies persist afterward.
Think of it as a route plan rather than a product brochure. A finance analyst pastes a client forecast into an approved assistant. A support platform calls a model API with ticket text. A retrieval system pulls three paragraphs from a shared drive into context. An agent opens a CRM record, then writes a summary into a ticketing tool. Each of those moments is a hop. Mapping names the hops, the data categories on each hop, and the people or services responsible for them.
Traditional application diagrams still help, but generative AI adds paths those older drawings rarely captured: free-text prompts, document uploads, embeddings, multi-step tool use, and provider-side logging. The map has to speak that language, or it will miss the exposures that matter most.
Why Map AI Data Before You Try to Govern It
You cannot govern what you cannot see. Enterprises often start with a model policy, a vendor checklist, or training about not pasting customer data into public chatbots. Those steps are useful. They are not a substitute for knowing which systems already touch contracts, claims files, source code, or HR notes.
Without a map, teams argue about risk in the abstract, audits get tribal knowledge instead of evidence, and controls land in the wrong place — a browser warning for employees while an internal app still sends full customer records through an unreviewed API.
Mapping makes later decisions cheaper: once you can point to the routes, you know where to minimize, anonymize, block, or justify private deployment. For keeping confidential information usable without default exposure, see how to safely use AI with confidential business data.
What Tracking AI Data Means Day to Day
Tracking is not a vanity dashboard. In practice it means you can answer, for each meaningful AI use case, a short list of concrete questions.
Where did the content originate — CRM, ticket system, file share, email, user paste, or another model? Who initiated the interaction — a named role, a service account, or an autonomous agent? What left the controlled environment, and in what form — raw text, protected text, embeddings, structured fields? Which model or provider processed it, under which contract and retention setting? What did the response contain, and who could see it? Were prompts, retrieved context, or outputs written to logs, traces, or analytics stores? How long do those secondary copies live, and who can query them?
If you can answer those questions consistently, you are already tracking AI data — whether or not you brand the artifact a “data flow map.” If you cannot, you are flying on hope, even with an AI committee and a polished slide deck.
The Paths a Serious Map Has to Cover
A usable map follows the paths where leakage and compliance questions actually arise.
Employee prompts and uploads. Chat interfaces and copilots remain the most visible route. An analyst pastes a customer list to reformat it. A lawyer uploads a draft agreement for clause extraction. The interaction looks like ordinary web traffic; the sensitive content is in the payload.
Application and API traffic. Internal products call models on behalf of users. Full records travel as JSON. No human reviews each field. If the map only covers “people using ChatGPT,” it misses the quieter, higher-volume path.
RAG and knowledge assistants. The user’s question may be clean while retrieved chunks are not. Document permissions, indexing scope, and chunk-level content belong on the map.
Agents and tool calls. Multi-step agents read systems, call APIs, and write results elsewhere. Each tool hop can forward identifiers the original user never typed into a prompt box.
Outputs and logs. Tracking includes what comes back and what gets stored for debugging or analytics. A sanitized input paired with a verbose log of the raw prompt is not a closed loop.
Training, fine-tuning, and evaluation sets. Where production data feeds those pipelines, they need their own routes, owners, and retention rules. When teams later place an AI privacy firewall or masking layer, these are the hops the control must cover — mapping first keeps you from protecting only the path you already understood.
How Enterprises Build and Maintain the Map
Most organizations do not need a six-month modeling project. They need a repeatable method that starts with reality and stays current.
Start with discovery, not architecture software. Interview teams that already use AI. Pull SaaS admin logs, API gateway records, browser or endpoint telemetry where available, and procurement lists of AI features inside existing tools. Shadow AI shows up here if you ask where people go when the approved option feels slow.
Inventory use cases next. Group them by purpose: support summarization, contract review, coding assistance, internal Q&A, customer-facing assistants, batch document extraction. For each use case, sketch the sequence in plain language before you draw boxes. “Ticket text → privacy check → model API → draft reply → agent console” beats a decorative diagram with vague arrows.
Classify the data on each hop. Names, account numbers, health details, credentials, source code, and strategy documents are not interchangeable. Classification is what lets you apply different protections without treating every string as equally radioactive. Techniques such as AI data masking only make sense once you know which fields and free-text patterns appear on which routes.
Mark trust boundaries — where content leaves your network, crosses a vendor, moves between regions, or enters a multi-tenant service. Assign a business owner and a technical owner to every route. Revisit on a cadence, or after any new AI feature launch, because copilots appear inside productivity suites and vendors change retention defaults.
This is also where AI DLP and privacy firewall choices become clearer: DLP-style visibility often helps you find routes; transformation controls help you change what travels on the highest-risk ones.
Flow Maps, Lineage, and Inventories
Teams sometimes use these terms as synonyms. They are cousins.
A system inventory lists AI applications, models, and vendors — what exists. Data lineage traces how a dataset or field was derived across warehouses and pipelines. AI data flow mapping focuses on interaction paths: what happens when a prompt is submitted, a document is retrieved, or an agent calls a tool, including copies that land in logs and provider infrastructure.
You need all three over time. An inventory without flows lists names without routes. Lineage without AI interaction paths may miss the chat window where someone pasted a customer file. Flow maps without lineage struggle when someone asks which training set fed a fine-tuned model.
The NIST AI Risk Management Framework emphasizes understanding context, data, and third-party components when mapping and measuring AI risk. Flow mapping turns that guidance into something an engineer and a compliance lead can both read.
Turning the Map Into Controls
A map earns its keep when it changes how data moves.
At high-risk hops — customer identifiers heading to an external model, health details in a summarization pipeline, secrets in code sent to a coding assistant place detection and protection before the model call. Minimization removes fields the task does not need. Masking, redaction, pseudonymization, or anonymization change what remains. Blocking fits credentials and other values that should never travel raw.
Centralize where you can. An AI gateway can become a consistent inspection and routing point across applications, which is easier to keep aligned with the map than a dozen one-off sanitizers. Close the loop on outputs and storage: if prompts land in an observability stack for thirty days, retention and access on that stack belong in the same conversation as the model vendor’s terms.
Use the map in vendor reviews. When a SaaS product enables an “AI rewrite” button, ask which fields leave, where they are processed, and whether your existing control points see that traffic. If the answer is “we’re not sure,” the map just found a new blank edge.
Blind Spots Worth Expecting
Even careful teams miss routes: embedded AI inside unrelated SaaS tools, contractors using personal assistants on shared files, evaluation copies of production samples left behind, and browser extensions that never touch the corporate gateway.
Over-trusting labels is another trap. We don’t train on your data” does not answer logging, retention, subprocessors, or whether your SIEM keeps full payloads. Tracking means following copies. Maps that stop at the model also miss restoration: if tokens map back to real names after inference, that reconciliation system needs vault-grade access control.
Governance Context (Educational, Not Legal Advice)
Flow maps support accountability. Under regimes such as the GDPR, organizations are expected to understand processing activities and apply data minimization — see the overview of principles at GDPR.eu. In the United States, the picture is more patchwork; teams often start with sector rules and state requirements summarized in guides like Questa’s US federal vs. state AI laws overview, then layer voluntary frameworks such as NISTs AI RMF.
This article is educational, not legal advice. Whether a given AI workflow meets a specific statute depends on the data involved, the legal and contractual context, the full control set, and counsel’s review. Mapping and technical privacy controls reduce unnecessary exposure and produce useful evidence; they do not, by themselves, make an organization compliant.”
When audit season arrives, a maintained flow map pairs well with a structured AI audit checklist: you can show routes, owners, protections, and residual gaps instead of reconstructing history from chat threads.
How Questa AI Fits Once the Routes Are Visible
Questa AI is built around a privacy-first layer: detect sensitive business data and anonymize it before it reaches an AI model, whether that model sits in the cloud or inside your own network. That only works as designed when you know which routes exist. Mapping tells you where to put the checkpoint; the anonymization engine is what changes the payload on those checkpoints.
Self-hosted Questa Blackbox fits enterprises that need the control inside their own perimeter; the Developer API embeds the same engine into products; Questa Cloud serves smaller teams that want safer querying of business data without running infrastructure. Across those shapes, the idea matches the map: protect sensitive content at the foundation, then let workflows run on the protected version.
Questa is one layer beside identity, DLP, gateway policy, and governance — not a replacement. The map keeps that layer honest about coverage.