Practices differ by vendor, architecture, configuration and contract, so none of these rows can be assumed. Microsoft’s documentation for Azure OpenAI shows why. It states that data stored at rest stays in the designated geography for all deployment types, while where prompts and responses are processed depends on the deployment type: global deployments may process data in any geography where the model is deployed, data zone deployments process within a specified zone, and regional deployments within the chosen geography. Its data privacy documentation makes the same distinction. The same service can therefore meet a storage requirement and fail a processing requirement if the wrong deployment type is chosen. Other vendors work differently, and documentation changes, so confirm the current terms for the specific product and plan.
Why AI data residency matters
Location determines which laws apply, which contractual promises must be honored, and what an organization can prove when asked. The most common failure is a mismatch: a contract tells a customer that data stays in one region, then an AI feature added later sends transcripts to a model provider elsewhere. No law has to be broken for that to breach the contract, and it usually surfaces during a customer security review, an audit or an incident, when the organization cannot give a documented answer.
Confidential business material carries similar exposure. Legal teams reviewing contracts or finance teams analyzing unreleased results with an AI tool are sending material with real competitive and legal weight. In regulated sectors, supervisors often expect firms to understand and oversee where regulated data is processed, particularly when third parties are involved. AI does not create that expectation, but it lengthens the processing chain and makes it harder to see.
There is also a practical cost. A business that cannot say where a vendor processes its data cannot assess its own regulatory exposure, and loses leverage when something has to be fixed quickly. Its own customers’ trust is hard to rebuild once they learn their data went somewhere they were not told about.
What GDPR and other rules do, and do not, require
GDPR does not require personal data to stay in the EU. Under Chapter V, personal data may only be transferred outside the EEA in line with specific conditions: transfers can rely on an adequacy decision or, without one, on appropriate safeguards such as Standard Contractual Clauses, with narrow derogations for certain situations. An EU business can therefore use an AI provider that processes data outside the EU if a valid mechanism is in place and documented. Keeping certain data in-region is often a risk-management or contractual choice layered on top of the law, not a GDPR rule.
For transfers to the United States, one available mechanism is the EU–US Data Privacy Framework, an adequacy decision covering certified US organizations. The EU General Court dismissed a challenge to it in September 2025 (Case T-553/23), and an appeal to the Court of Justice (Case C-703/25 P) was reported as pending at the time of writing. Organizations relying on it should track that case and know which fallback, such as Standard Contractual Clauses, they would use.
Location is also not the same as compliance. Residency is about where data sits. Data protection covers purpose limitation, data minimization, security and processor terms, including controls over subprocessors. Lawful transfers concern the mechanism for moving data across borders. Broader compliance adds a lawful basis for processing, impact assessments where required, and sector rules. Storing data in a particular country satisfies none of these automatically.
Some countries and sectors, including finance, health, telecom and public-sector contracting, add their own location, outsourcing or access requirements. They differ and they change, so confirm which apply with qualified counsel. This article is general information, not legal advice.
How businesses control where AI data resides
Region and deployment controls. Many vendors let customers choose a region or data zone for processing. That is a necessary first step, but confirm that logs, caches, vector stores and backups inherit the same restriction, because they do not always.
Infrastructure you control. Running AI workloads on cloud accounts you manage lets you pin storage and compute to a region and check it yourself instead of relying on a vendor statement.
Private or on-premises deployment. Keeping processing inside your own network removes a third-party data path, provided the model, the vector store and the logs all run there too. It also brings operating responsibilities: capacity, patching and model updates.
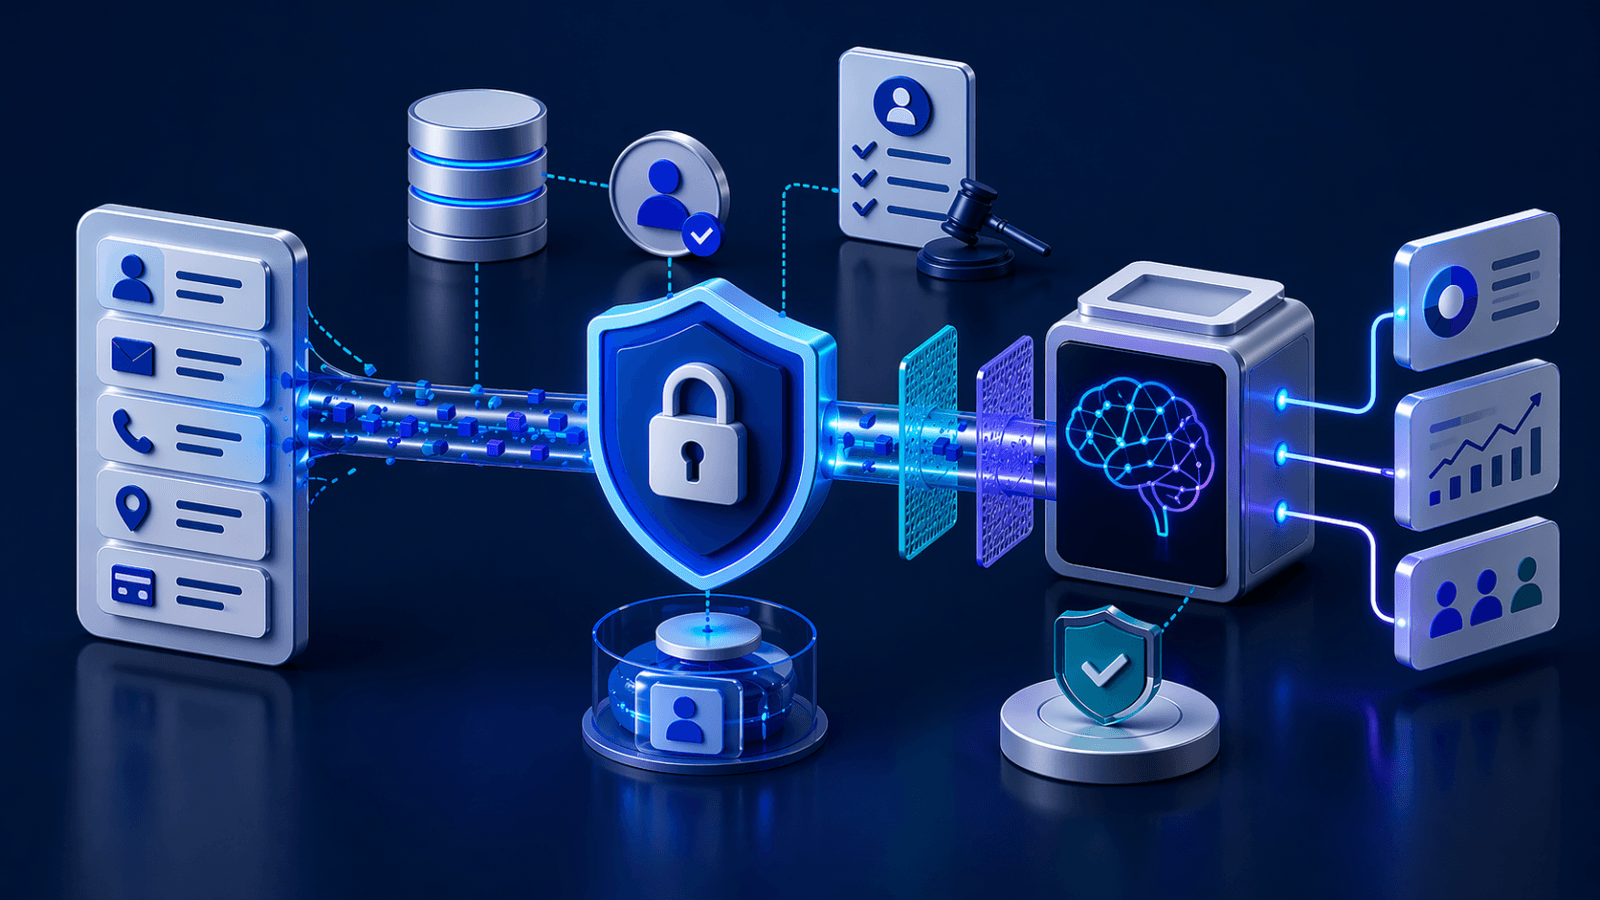
Minimization and anonymization. Removing or replacing identifiers before data leaves your environment reduces what is exposed. It has limits, though. Tokenized or pseudonymized data can remain personal data under GDPR if it can be re-identified, so it does not remove the need for transfer analysis, and true anonymization is a high bar.
Contracts and access controls. Useful terms include processing-location commitments, advance notice and objection rights for subprocessor changes, failover terms, limits on support access, and customer-managed encryption keys where offered. A contract helps only if the vendor can demonstrate the technical behavior behind it.
Technical enforcement. Network egress controls, an internal gateway, or policies that restrict which AI endpoints applications may call make residency rules testable rather than aspirational.