FEB 02, 2026Updated Oct 21, 2026

How LLM Data Anonymization Protects Sensitive Information

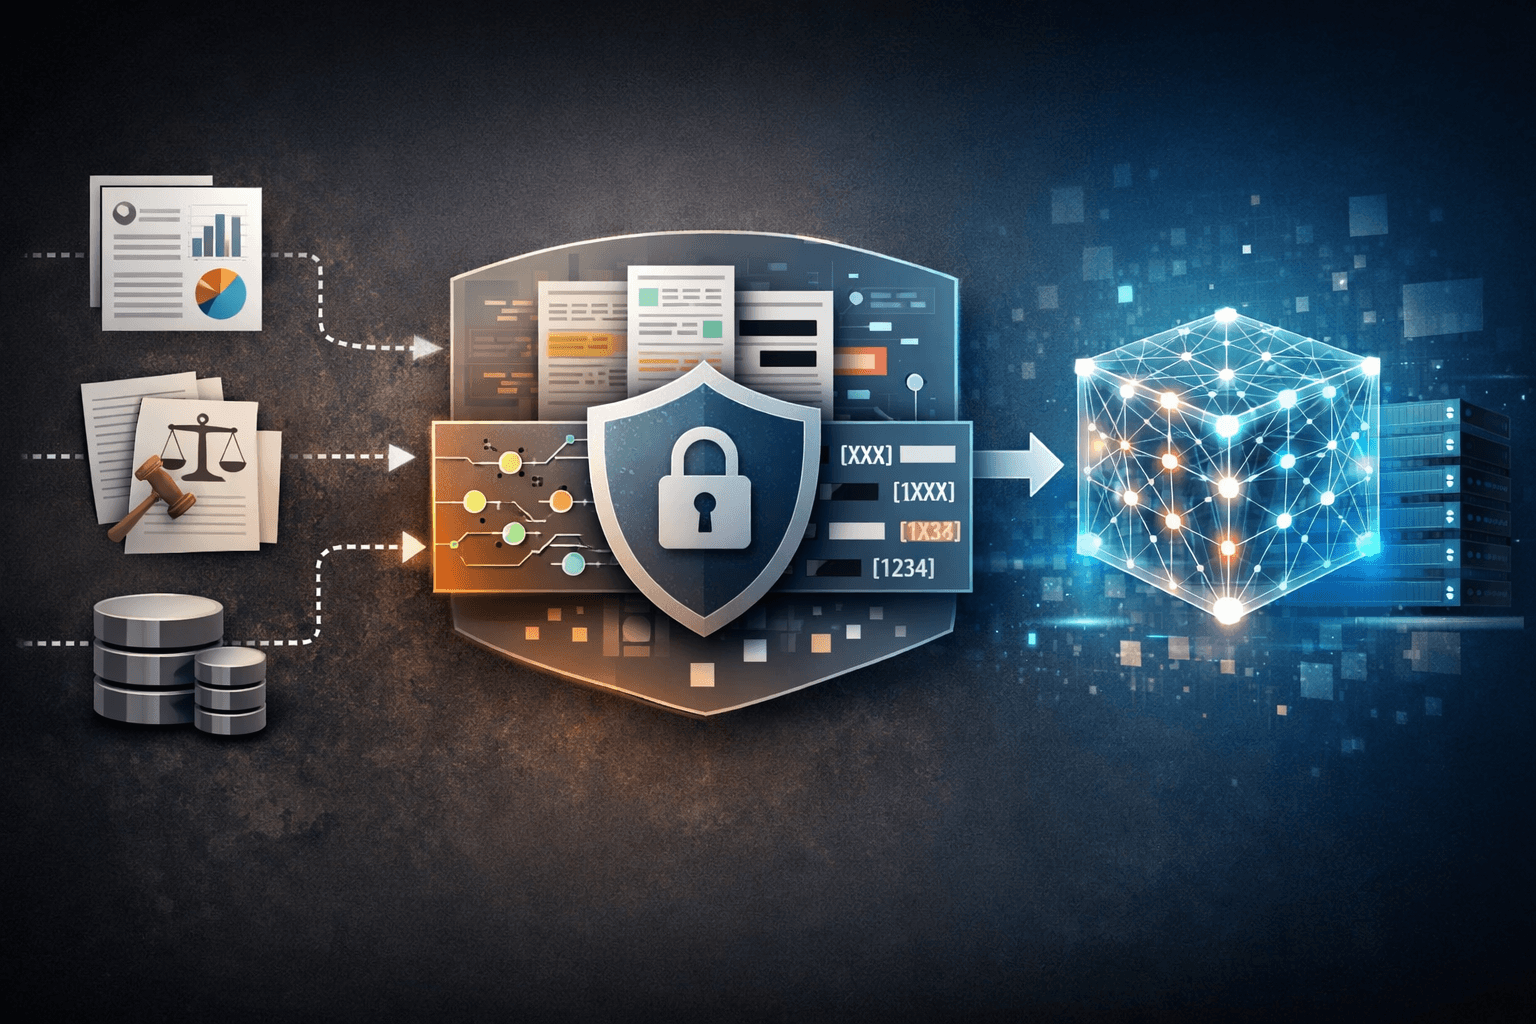
LLM data anonymization detects sensitive information such as names, contact details and identifiers, and removes or replaces it before text, documents or spreadsheets reach a language model. This article looks at how that works in Questa AI's anonymizer: two complementary detection models, a rule-based way to resolve overlapping entities, specific handling for CSV and Excel files, and reconstruction of PDF, DOCX and XLSX outputs. It also covers how to test an anonymizer before relying on it, and what anonymization cannot guarantee.

BPOs (1)

Key Takeaways

  • LLM data anonymization protects sensitive information before it reaches AI models.
  • A general NER model and a specialised PII model catch different entity types, so running both covers more than either alone. How much more should be measured on your own data.
  • Overlapping detections need a deterministic resolution rule, and replacements must be applied without shifting offsets.
  • Structured files such as PDFs, Excel spreadsheets, and CSVs require specialized anonymization techniques.
  • Detection and replacement do not guarantee anonymity. Accuracy has to be measured per entity type, and residual risks remain.
  • Data anonymization helps organizations reduce privacy and compliance risks when using AI.
  • Privacy-preserving AI workflows enable safer adoption of large language models across regulated industries.

Key Concepts Before You Read On

Four ideas recur throughout this article, and each has a precise meaning in an anonymization pipeline.

PII (personally identifiable information) is any data that can identify a person, alone or combined with other data. Direct identifiers such as names, email addresses and ID numbers point to someone on their own. Indirect identifiers, such as a job title, an employer and a date, identify someone only in combination.

Named entity recognition (NER) is a task in which a model reads text and labels pieces of it with entity types such as person, organization or location. General NER models are trained on those broad categories, which is why a dedicated PII model is used alongside one here.

Entities, spans and offsets. A detected entity is a span of text with a label, recorded as start and end character positions (offsets) in the original string. Everything later in the pipeline, from merging overlaps to replacing text, works on these offsets, so mishandling them corrupts the output.

Precision and recall. Precision is the share of redacted items that were truly sensitive. Recall is the share of sensitive items that were caught. In anonymization, low recall means sensitive data left in the output, and low precision means useful context removed.

The difference between redaction, masking, pseudonymization and anonymization is covered later, in the section on what anonymization does not guarantee.

The Pipeline at a Glance

Anonymizing a document involves more than detection. The table shows which stages this article describes and which a production deployment should add.

The Pipeline at a Glance
StageStatusNotes
Parsing by formatDescribedpdfplumber, python-docx, openpyxl, CSV
DetectionDescribedNER and PII models; regex and header rules for tabular data
Span mergingDescribedmerge_entities
ReplacementDescribedCategory placeholders such as [PER] and [LOC]. Policy per entity type is not described.
ValidationRecommendedLeak tests and structure checks (see the evaluation and reconstruction sections)
ReconstructionDescribedPDF via reportlab, Excel via openpyxl
Delivery to the LLM or applicationOut of scopeNot covered in this article
Logs, temporary files, errorsRecommendedNo raw text in logs, short retention

The Core: A Dual-Model Approach to PII Detection

We realized early on that a single Natural Language Processing (NLP) model wasn't enough to catch everything. General Named Entity Recognition (NER) models are great at finding people and locations, but they often miss specific PII patterns like email addresses or ID numbers.

To solve this, we implemented a composite pipeline in anonymize/core.py that loads two distinct Hugging Face models:

NER Model: elastic/distilbert-base-uncased-finetuned-conll03-english (optimized for standard entities like Persons, Organizations, Locations).

PII Model: iiiorg/piiranha-v1-detect-personal-information (specialized for sensitive personal data detection).

The Merge Logic

Running two models introduces a new problem: overlapping entities. If Model A says characters 10-15 are a [NAME] and Model B says characters 12-20 are an [EMAIL], naïve replacement will break the string.

We wrote a custom merge_entities algorithm in anonymize/text.py. It sorts entities by their start position and resolves conflicts by prioritizing the longest span and ensuring no "dead space" exists between merged entities.

This ensures that when we redraw the text, we get clean, non-overlapping tokens like [PER] or [LOC], rather than corrupted text.

Why Offsets Break: A Worked Example

Detectors report entities as character offsets into the original string, with the end offset exclusive. Overlaps are common, because a name model and a PII model look at the same characters with different definitions of an entity. Take this 46-character sentence:

Reach Maria Chen at maria.chen@acme.com today.

The NER model returns PER for characters 6-16 ("Maria Chen") and, plausibly, PER for 20-30 ("maria.chen"), the name-like start of the email address. The PII model returns EMAIL for 20-39. The last two spans are nested, with one entity entirely inside the other.

If replacements are applied in arrival order, every replacement changes the string's length and every later offset points at the wrong characters. Replacing 6-16 with [PER] shifts everything after it five characters to the left. The second PER span then cuts into the middle of the email address, and the EMAIL span lands on the wrong text. The output is:

Reach [PER] at maria[EMAIL]

Part of the email address survives, " today." is lost, and no error is raised. The output is both leaky and corrupted.

Two rules prevent this. First, resolve conflicts on the original offsets before touching the text, producing a set of non-overlapping spans. Second, apply replacements from the end of the string to the start, or build the output by slicing the original, so a replacement can never move a span that has not been applied yet. Here the nested PER span is absorbed by EMAIL, and the output is Reach [PER] at [EMAIL] today. A minimal illustration (not the production merge_entities code):

PRIORITY = {"EMAIL": 3, "ID": 3, "PHONE": 3, "PER": 2, "LOC": 1}  # example policy

def resolve(spans):  # spans: (start, end_exclusive, label, score)
    out = []
    for s in sorted(spans, key=lambda x: (x[0], -x[1], x[2])):
        if out and s[0] < out[-1][1]:  # overlaps the previous span
            p = out[-1]
            best = max((p, s), key=lambda x: (PRIORITY.get(x[2], 0), x[3]))
            out[-1] = (p[0], max(p[1], s[1]), best[2], best[3])
        else:
            out.append(s)
    return out

def apply(text, spans):
    for start, end, label, _ in sorted(spans, reverse=True):
        text = text[:start] + f"[{label}]" + text[end:]
    return text

Choosing the resolution rule. Longest-span-wins is a sensible default, but it is not universally correct. A long span from a low-confidence detector can swallow a short, high-confidence identifier. A robust rule considers entity type first (an email or ID should win over a name label inside it), then detector confidence, then length, then a fixed tie-break such as start offset and label, so the same input always gives the same output. Partial overlaps need an explicit policy too. Merging into the union of both spans, labelled with the higher-priority type, avoids leaving fragments of either entity, at the cost of occasionally redacting a few extra characters. The redaction policy decides whether that trade is acceptable.

Testing the merge. Use fixed cases: nested spans, partial overlaps, identical spans with different labels, adjacent spans, spans at the string boundaries, and text with multi-byte characters, where byte and character offsets diverge. Add randomly generated overlapping spans. Useful invariants are that no character from any detected span survives in the output, that no partial placeholder appears, and that the result does not depend on the order detections arrive in.

Handling Structured Data: The CSV Challenge

Anonymizing a PDF is hard, but anonymizing a CSV or Excel file is deceptively difficult. You cannot simply pass a CSV string to an LLM or an NLP model; the lack of sentence structure confuses the context-aware models. We adopted a hybrid approach in anonymize/csv.py that combines heuristic rules with NLP, processed via multithreading for performance.

1. Multithreaded Row Processing

NLP inference is CPU-bound and slow. Processing a 10,000-row CSV sequentially would take forever. We utilized Python's ThreadPoolExecutor to redact rows concurrently.

# From anonymize/csv.py
with ThreadPoolExecutor(max_workers=MAX_THREADS) as executor:
    futures = {executor.submit(redact_row, row): idx for idx, row in enumerate(df_sample)}
    # ... process results as they complete ...

2. Smart Heuristics

For structured data, we don't rely solely on the models. Specific logic handles common fields, which saves compute and is more predictable than model inference for well-defined formats.

Emails: Detected via regex patterns (@ symbols) and strictly redacted.

Headers: We check column headers. If a column is named "Full Name," we force a [PER] redaction even if the model is unsure.

Numerics: Purely numeric cells are currently skipped, so amounts, balances and quantities stay usable for AI in financial reporting and compliance workflows.

The numeric rule is a trade-off, not a safe default. Numbers are not inherently non-sensitive. A ten-digit value in a "Contact" column is a phone number, a 9-16 digit value may be an account, card or national identifier, and identifiers stored as numbers are common in spreadsheets. A salary or invoice total on its own is usually not personal data, though it can become identifying alongside a role or date. A context-aware policy is safer than skipping by data type. It reads the header and neighbouring columns to decide whether a numeric column is an identifier or a measure, and runs format validators (such as the Luhn check for card numbers or the IBAN checksum) on numeric-looking values. It also defaults to redaction where the context is ambiguous, and preserves numeric columns only once they are confirmed to be measures.

3. Column-Level Thresholding

This is my favorite feature. Once we process a sample of the data, we calculate a "redaction ratio" for each column. If more than 80% of a column contains PII (e.g., a column of home addresses), we don't bother processing the rest. We wipe the entire column and replace it with the most common placeholder (e.g., [ADDRESS]).

The threshold is a heuristic computed from a sample, and it trades leakage risk against data utility. Three limits are worth knowing. The ratio depends on detector recall: if the models miss a third of the values in an address column, the measured ratio falls below the threshold, the column is processed cell by cell, and the same misses stay in the output. A sample that is not representative, such as the first rows of a file sorted by date or region, can misjudge the whole column. And wiping a column replaces every distinct value with one placeholder, which protects the values but removes the ability to group, join or deduplicate on that column.

The 80% figure is therefore a starting point for one use case, not a standard. A deployment may reasonably use a much lower threshold, or any detection at all, for columns whose headers mark direct identifiers, and a higher one for free-text columns where PII is sporadic.

The granularity of masking should follow the data. Column-level masking suits homogeneous identifier columns such as addresses or account numbers. Cell-level masking suits mixed or free-text columns, such as notes, where sensitive values appear occasionally among useful text. Row-level masking suits cases where sensitivity belongs to the record rather than a field, for example a person who has withdrawn consent, or a row whose combination of fields would identify someone even with the names removed.

4. Headers, Missing Values and Malformed Rows

Headers and cell contents are separate signals. A header such as "Full Name" is a strong prior, but headers like "Col3", "Notes" or "Ref" say little, and cell content can contradict them. Headers can also contain PII, for example in pivoted tables where customer names are column labels, so they should be scanned like any other text.

Empty cells and placeholders such as "N/A" should not count toward a column's redaction ratio. Malformed rows deserve more care: a ragged CSV line or an unquoted delimiter can shift a value into the wrong column, so a header-based rule is applied to the wrong data and an address can end up in a "Notes" field. A safe pipeline fails closed on such rows, quarantining or flagging them rather than passing them through. Inconsistent formatting, such as phone numbers with and without separators, identifiers with spaces, dates in mixed formats and numbers stored as text, belongs in the test set, because each is a way for a detector to miss.

File Reconstruction

We support .docx, .pdf, and .xlsx. The challenge here isn't just reading the text, but putting it back together without breaking the file format.

This capability is particularly valuable for healthcare organizations, financial institutions, and enterprises processing sensitive documents.

For PDFs, we use a sequence of pdfplumber to extract text, pass it through our anonymize pipeline, and then use reportlab to generate a brand new PDF stream containing the safe, categorized text.

For Excel, we deconstruct the workbook into DataFrames, process them using the CSV logic mentioned above, and then reconstruct the workbook using openpyxl, preserving the sheet structure.

What Reconstruction Can Leak

Rebuilding a file is a privacy step in its own right, because a document carries more than its visible text, and how the output is produced decides what survives.

Generating a new PDF with reportlab from extracted text, as described above, has a useful side effect. Anything the extractor did not return, such as document properties, annotations, form fields or embedded files, is not copied into the new file unless the code adds it. The cost is fidelity: layout, tables and images are not preserved, and a scanned PDF with no text layer gives pdfplumber nothing to extract, so image-only pages need OCR and the same detection before they can be handled. Editing a document in place preserves more, but also keeps everything you do not explicitly clean: tracked changes, comments, headers and footers, document properties and embedded objects in DOCX.

Spreadsheets have more hiding places: hidden sheets, rows and columns, cell comments, formulas, defined names and document properties such as the author. Loading sheets into DataFrames and writing a fresh workbook typically drops comments, defined names and properties unless the code copies them, and returns formula results rather than formula text. Whether hidden sheets are read and processed or skipped should be confirmed, not assumed.

Whichever route is used, validate the result. Reopen the output with the same parser, check that sheet names, row and column counts and header positions match the input (allowing for deliberately removed columns), and search the raw output, including its metadata and XML parts, for known test identifiers.
Evaluating an Anonymizer Before You Rely on It

Whether an anonymizer is good enough is an empirical question, and the answer is specific to your documents.

Test data. Build a labelled set from documents that resemble real inputs, labelled at the span level by entity type. Real documents must be access-controlled. Synthetic or already de-identified documents are safer, but synthetic text tends to be cleaner than production data, so include realistic mess: OCR errors, inconsistent formats, abbreviations and names from different languages and cultures.

Scoring. Precision is the share of redacted spans that were genuinely sensitive. Recall is the share of sensitive spans that were redacted. F1 combines them. Report them separately for names, email addresses, phone numbers, financial identifiers, addresses and any domain-specific entities such as case or patient numbers. Decide the match criteria in advance: a prediction that covers an entire account number but with slightly different boundaries is acceptable, while one that leaves half of it visible is a leak.

Treat errors asymmetrically. A false negative leaves sensitive data in the output. A false positive removes context the downstream model needs and degrades its answers. Weigh misses by severity: a missed national ID number is not equivalent to a missed first name.

An overall F1 score does not show that a system is safe. A high aggregate can coexist with poor recall on a rare, high-severity type. Set a minimum recall per entity type according to the harm of exposure.

Coverage and leakage. Run the same content as free text, PDF, DOCX and spreadsheets, since failures cluster at format boundaries such as table cells, headers and footers and extraction order. Plant synthetic identifiers in test files and search the entire final output, including metadata, for them. Check language support: the NER model used here is fine-tuned on English CoNLL-2003 data and is uncased, so it cannot use capitalisation as a cue. Confirm each model's supported languages on its model card and evaluate other languages separately.

Regression and review. Keep the labelled set fixed and re-run the suite whenever a model, rule, threshold, policy or parser version changes, storing results per version. For high-risk material, such as health, legal or financial records, add human review of sampled outputs.

What Anonymization Does Not Guarantee

Detecting and replacing identifiers lowers risk. It does not prove that a document can no longer identify anyone.

The terms describe different outcomes.

  • Redaction removes a value, and the output records nothing about what it was.
  • Masking obscures part or all of a value, often preserving its format.
  • Pseudonymization replaces an identifier with a substitute while a way to reverse it, such as a mapping table, still exists. Under GDPR (Article 4(5)), pseudonymised data is still personal data.
  • Anonymization describes the result, not the technique: individuals cannot be identified by any means reasonably likely to be used (Recital 26).

A pipeline that swaps names and email addresses for placeholders performs redaction or pseudonymization. Whether its output is anonymous depends on what remains. The pipeline described here replaces values with category placeholders such as [PER] and describes no mapping store. Adding reversible tokens would make it pseudonymization, and the mapping and re-identification step would need restricted, logged access and a location the model provider cannot reach. AI Anonymization vs Redaction compares the approaches in more detail.

Residual risks fall into a few groups:

  • Missed identifiers. No detector has perfect recall. Unusual formats, rare names and local ID schemes are the usual misses.
  • Indirect identification. A job title, employer and date together can single someone out with no name present.
  • Context in free text. A description such as "the only partner in the Anand office" contains no entity a model will flag.
  • Metadata, comments and extracted text. These carry PII that never appears in the visible body.
  • Retained mappings and replacement values. Where tokens are reversible, anyone holding the mapping can re-identify.
  • The anonymizer's own footprint. The service handles raw data before it is protected, so uploads, temporary files, exception traces and debug logs must be treated as sensitive. Keep retention short and keep raw text out of logs. Prompts and model outputs also need review for data leaking back out.

Treat anonymization as one control alongside data minimisation, access control, retention limits and human review for high-risk material. A document is not anonymous because the obvious names and email addresses are gone.

Why This Matters

By combining specialized NLP models with file-specific heuristics and concurrent processing, we reduce the identifiable information that reaches an AI model while keeping enough structure for it to stay useful. This allows organizations to leverage advanced AI models without sending raw identifiers to the model, helping support secure AI adoption across regulated industries.

The code is designed to be modular. Whether we are processing a raw string, a complex legal PDF, or a financial spreadsheet, the pipeline normalizes the input, sanitizes it, and reconstructs it, ensuring that Questa AI remains a secure gateway for enterprise AI.

Technical Summary

Stack: Python, FastAPI, Hugging Face Transformers, PyTorch.

Models: DistilBERT (NER) + Piiranha (PII).

Concurrency: ThreadPoolExecutor for structured data.

Parsers: pdfplumber, openpyxl, python-docx.

Frequently Asked Questions

LLM data anonymization removes or replaces sensitive information before content is processed by AI models.

Anonymization helps reduce privacy, security, and compliance risks when working with sensitive information.

It can help, but it depends on the result. Data that is genuinely anonymous falls outside GDPR, while pseudonymized data, such as placeholders backed by a reversible mapping, remains personal data. Whether an output counts as anonymous depends on whether individuals can still be identified by means reasonably likely to be used. Anonymization is one control among several and is not a compliance guarantee on its own.

Organizations often use anonymization, governance controls, and secure workflows to protect sensitive information before AI processing.

Healthcare, financial services, legal services, customer support, and other regulated industries frequently use data anonymization before AI processing.

Test it on a labelled set of documents that resembles your real data, and score detection per entity type, because an overall F1 score can hide weak recall on a rare but sensitive type such as national ID numbers. Count missed entities (sensitive data left in the output) separately from over-redaction, test every file type you will accept, plant known test identifiers to check the final output for leaks, and re-run the suite whenever a model, rule or policy changes. For high-risk material, add human review.

Pseudonymization replaces identifiers with substitutes while a way to reverse the substitution still exists, such as a mapping table, so under GDPR the data remains personal data. Anonymization means individuals can no longer be identified by any means reasonably likely to be used, and it describes the resulting data rather than the technique. Replacing names with placeholders such as [PER] is redaction or pseudonymization. It becomes anonymization only if the remaining content cannot identify anyone.

No. Models miss unusual formats, rare names and identifiers they were not trained on, and entity detection cannot remove information that identifies a person only through context or a combination of attributes. Rule-based checks, per-type testing, careful handling of metadata and logs, and human review for high-risk documents reduce the residual risk but do not eliminate it.

Conclusion

An anonymizer is only as trustworthy as its weakest stage. Two complementary models cover more entity types than either alone, but their outputs must be reconciled with a deterministic rule and applied without shifting offsets, or the result is corrupted and can still leak. Structured files need context-aware handling: numeric columns can hold identifiers, column thresholds trade leakage risk against utility, and malformed rows should fail closed. Rebuilding a file is a privacy step in itself, because metadata, comments, hidden sheets and scanned pages can carry data that detection never sees.

Before relying on any anonymizer, measure it. That means per-entity precision and recall on representative documents, leak tests on the final output, regression checks after every model, rule or policy change, and human review where the stakes are high. It also means describing the result accurately: replacing names and email addresses with placeholders reduces risk, but it does not make a document anonymous. Anonymization works best as one control among several, alongside data minimisation, access control and retention limits, when organizations need to use LLMs with sensitive documents.

Abhi Author

About the author:

Abhiroop Sharma

Ex. Distinguished technology leader

Distinguished technology leader with 18+ years of progressive experience spanning AI, Web3, SaaS, eCommerce, and blockchain governance. Demonstrated success in driving digital transformation across global markets, with expertise in scaling enterprise solutions from concept to implementation. Proven track record of reducing implementation timelines by 50% and building high-performing teams across multiple organizations. Currently focused on pioneering AI implementation and Web3 integration strategies for emerging technology ventures.
Follow the expert:

Related Articles

View More
AI Data Anonymization: Why It's Critical for Enterprise AI
JUN 10, 2026
Privacy Cafe

AI Data Anonymization: Why It's Critical for Enterprise AI

AI data anonymization reduces sensitive data exposure in enterprise AI, but it isn't foolproof. See what it actually protects—and what it doesn't.

Read More
AI Security Governance: A New Enterprise Security Priority
JUN 01, 2026
Privacy Cafe

AI Security Governance: A New Enterprise Security Priority

AI security governance covers agent access, identity, and data risk. See what it means and how to build a working framework for your enterprise.

Read More
Enterprise AI Legal Risk: How to Assess & Manage It
MAR 05, 2026
Privacy Cafe

Enterprise AI Legal Risk: How to Assess & Manage It

Enterprise AI creates legal exposure beyond data security — privacy, IP, vendor terms, bias, and governance gaps — plus a practical framework to manage each.

Read More