AI model routing is a control layer that sits between an application and a pool of approved AI models. It evaluates each request and directs it to the model best suited to handle it — based on task complexity, required capability, cost, latency, data sensitivity, data residency, and organizational policy, not on price alone.
Most discussions of routing treat it as a cost-cutting trick: send everything to the cheapest model possible. That framing is incomplete. A router built purely for cost will eventually send a compliance-sensitive document to an unapproved provider, or a genuinely hard reasoning task to a model that can't do it reliably. The more useful framing: the cheapest model is not always the right model. The best route is the model that satisfies the task and the organization's policy.
How Routing Works
A simplified architecture:
Application → AI Gateway / Router → Approved Model Pool → Response → Application
The router doesn't generate the response — it decides which model will. A simple classification task might go to a small, low-cost model. A complex reasoning task might go to a more capable one despite higher cost. A request containing sensitive data might be restricted to an approved private or regional model regardless of what cost logic would otherwise pick. A critical workflow — a clinical or legal decision step — might bypass automatic routing entirely and stay pinned to one validated model.
The terminology overlaps: LLM router, model router, and inference router are often used interchangeably, though "inference router" sometimes refers to lower-level load balancing rather than task-aware selection. Treat vendor language as inconsistent and ask what a given product actually does.
Sending every task to one model — usually the most capable, as the "safe" default — means paying premium prices for tasks that don't need premium capability. It's tempting to attach a specific savings percentage to fixing this, but the honest answer depends on traffic composition, real pricing gaps, routing accuracy, escalation rate, output-token volume, cache hit rate, and router overhead. Measure it against your own workload, not an industry figure.
The Seven Signals a Router Should Weigh
- Task complexity — how hard is the request, independent of type?
- Required capability — reasoning, coding, multimodal input, tool use, long context?
- Data sensitivity — PII, financial data, health information, credentials, trade secrets?
- Data residency — where is this data allowed to be processed?
- Latency — real-time or asynchronous?
- Cost — what's the acceptable budget?
- Business risk — what happens if the model gets it wrong?
These don't collapse into one score. A request can be low-cost-sensitivity but high-business-risk, or low-complexity but high-data-sensitivity. A router optimizing a single blended metric will eventually route a "simple" request containing regulated health data to whatever's cheapest, without checking eligibility first.
Cost and Quality Have to Move Together
Cost-aware routing means choosing the lowest-cost model that reliably meets a task's quality bar — not the cheapest model available. That distinction only holds if quality is actually being measured: evaluation sets that reflect real production traffic, task-specific thresholds, confidence signals that trigger escalation rather than returning a shaky answer as final, and ongoing monitoring once a route is live.
If a small model shows strong, validated accuracy on narrow ticket classification, there's little reason to route that work to a premium model. A legal workflow requiring careful reasoning calls for a different bar — decent performance on a general benchmark says little about reliability on that specific task. Route based on demonstrated capability, not model size.
Privacy-Aware Routing
Privacy-aware routing extends the router's evaluation to the data in a request, not just the task. A request containing salary history or health information might be routed to an approved private model, a regional deployment, a minimized version sent to a broader pool, human review, or blocked outright — depending on policy.
Be precise about limits here: routing sensitive data to a private or local model doesn't by itself make a workflow GDPR-compliant, and a local model isn't automatically compliant just because it's local. Data residency (where data sits) isn't the same as data sovereignty (whose laws govern it). Routing enforces an organization's own policy about where data can go — a real control, but one piece of a compliance program, not a substitute for one.
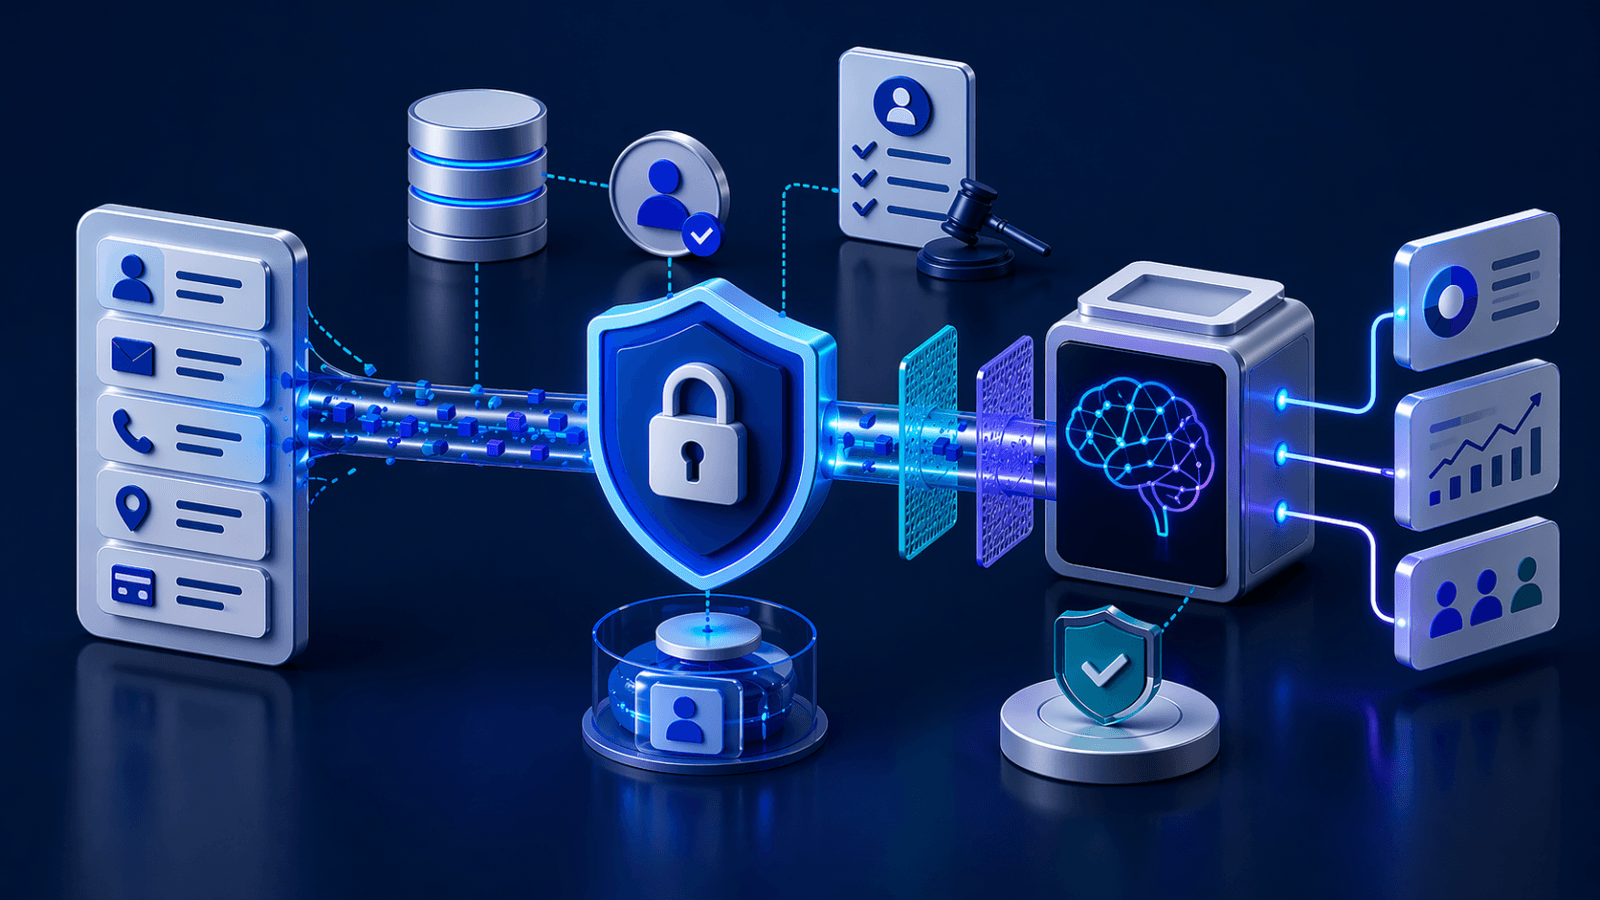
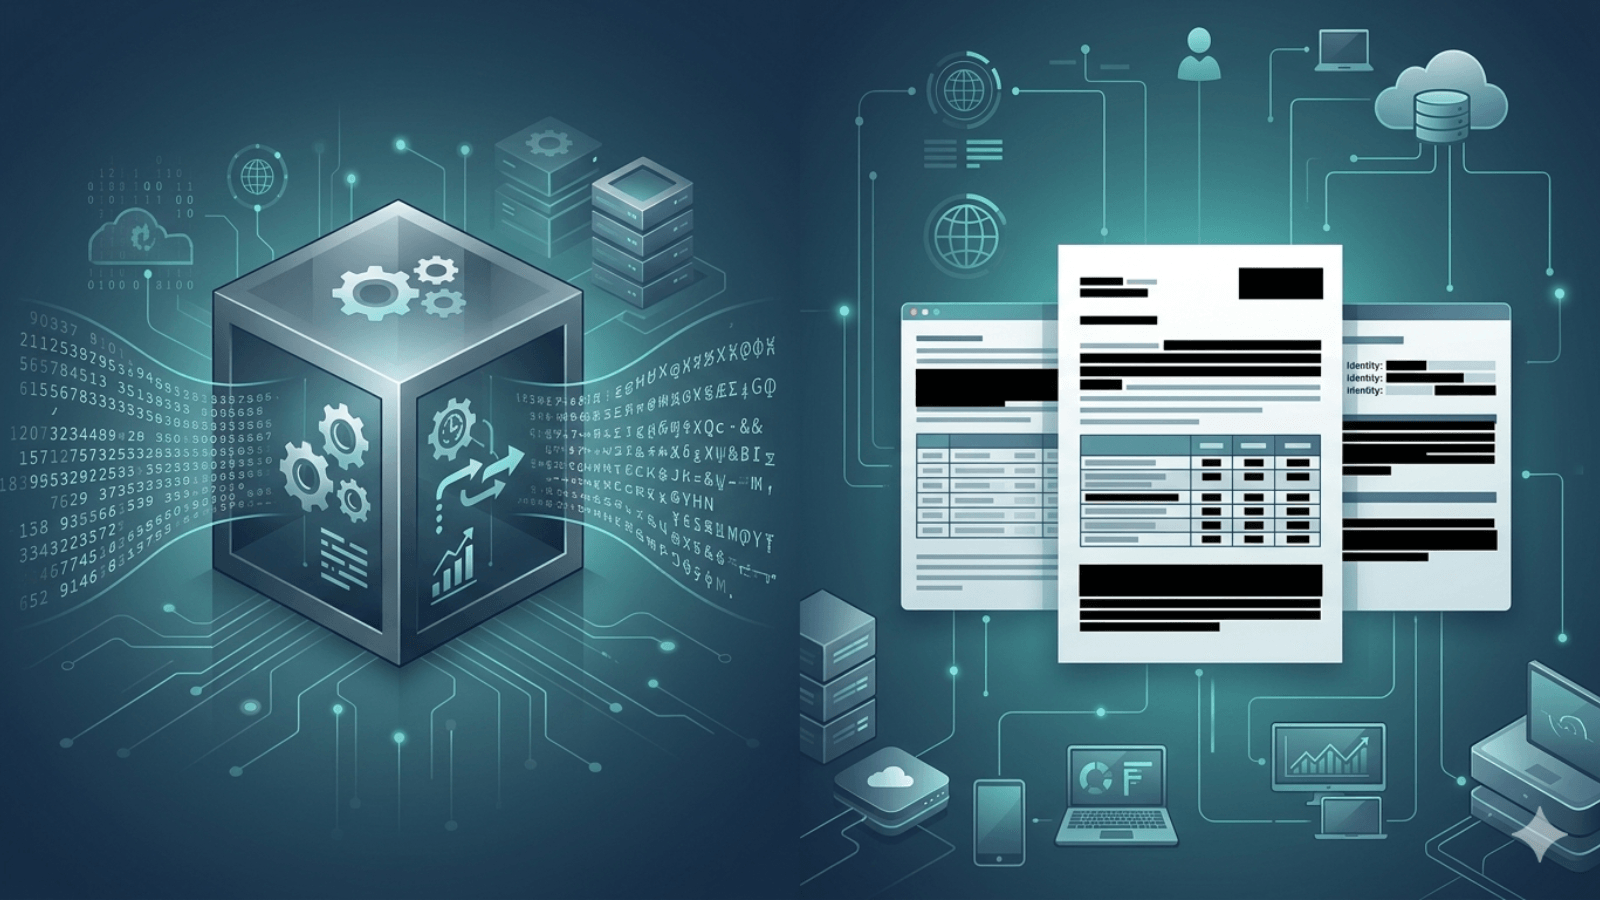
Routing controls where a request goes. Redaction controls what travels with it. Most architectures need both — a privacy layer strips identifiers a model doesn't need, and the router then sends the sanitized request to an approved model. This is the pattern Questa AI's privacy-first architecture is built around: minimizing what a model sees, alongside controlling which model sees it. Neither replaces the other.
Fallback Is Where Privacy Controls Usually Break
What happens when a selected model times out, hits a rate limit, or fails a quality check? The principle: fallback must respect the same policy constraints as the original decision. A router should never start with an approved private model for sensitive data and, on failure, silently fall back to an unapproved public one just because it's available. That defeats privacy-aware routing at the exact moment the safeguard matters. Fallback pools need the same residency, provider, and capability constraints as the primary route, defined in advance.
Routing for Agents, Briefly
Agentic workflows generate multiple model calls per task — planning, retrieval, tool use, reasoning, summarization — and each step can have different requirements. This argues for routing per step, not once for a whole session; assuming one model selection holds for an entire agentic task tends to produce either wasted cost or unmanaged risk somewhere in the chain.
A Note on Caching
Semantic caching — serving a stored response when a new prompt means roughly the same thing as a prior one — can reduce repeated inference, but only as much as the traffic is genuinely repetitive. It's worth remembering that a cache is itself a data store: it needs the same access controls and retention rules as the models it sits next to, because stale answers, cross-tenant leakage, and lingering sensitive prompts are real risks, not edge cases.
Where Questa AI Fits
A model router determines where AI processing happens. A privacy layer determines what data is exposed during that processing. A well-designed router can send sensitive requests to appropriately approved models and still expose more raw data than necessary, because nothing upstream reduced that exposure first. Questa AI's role is that upstream step — minimizing unnecessary sensitive information before it reaches any model, so the routing decision and the minimization decision reinforce each other rather than duplicating effort.
To be direct: this doesn't automatically make an organization compliant with any regulation, and it doesn't eliminate the risk of using AI for consequential decisions. It gives more control and visibility over two things that matter most — where a request goes, and what it carries with it.
Quick Checklist
- Inventory AI workloads and classify by complexity and sensitivity
- Define approved model pools per use case, not a single shared pool
- Set geographic and provider restrictions as hard constraints
- Define fallback rules that mirror primary-route policy
- Monitor quality, cost-per-successful-task, and policy violations by route — not token cost alone