APR 08, 2026Updated Sep 14, 2026

GraphRAG vs Vector RAG: Which Is Better for Enterprise AI?

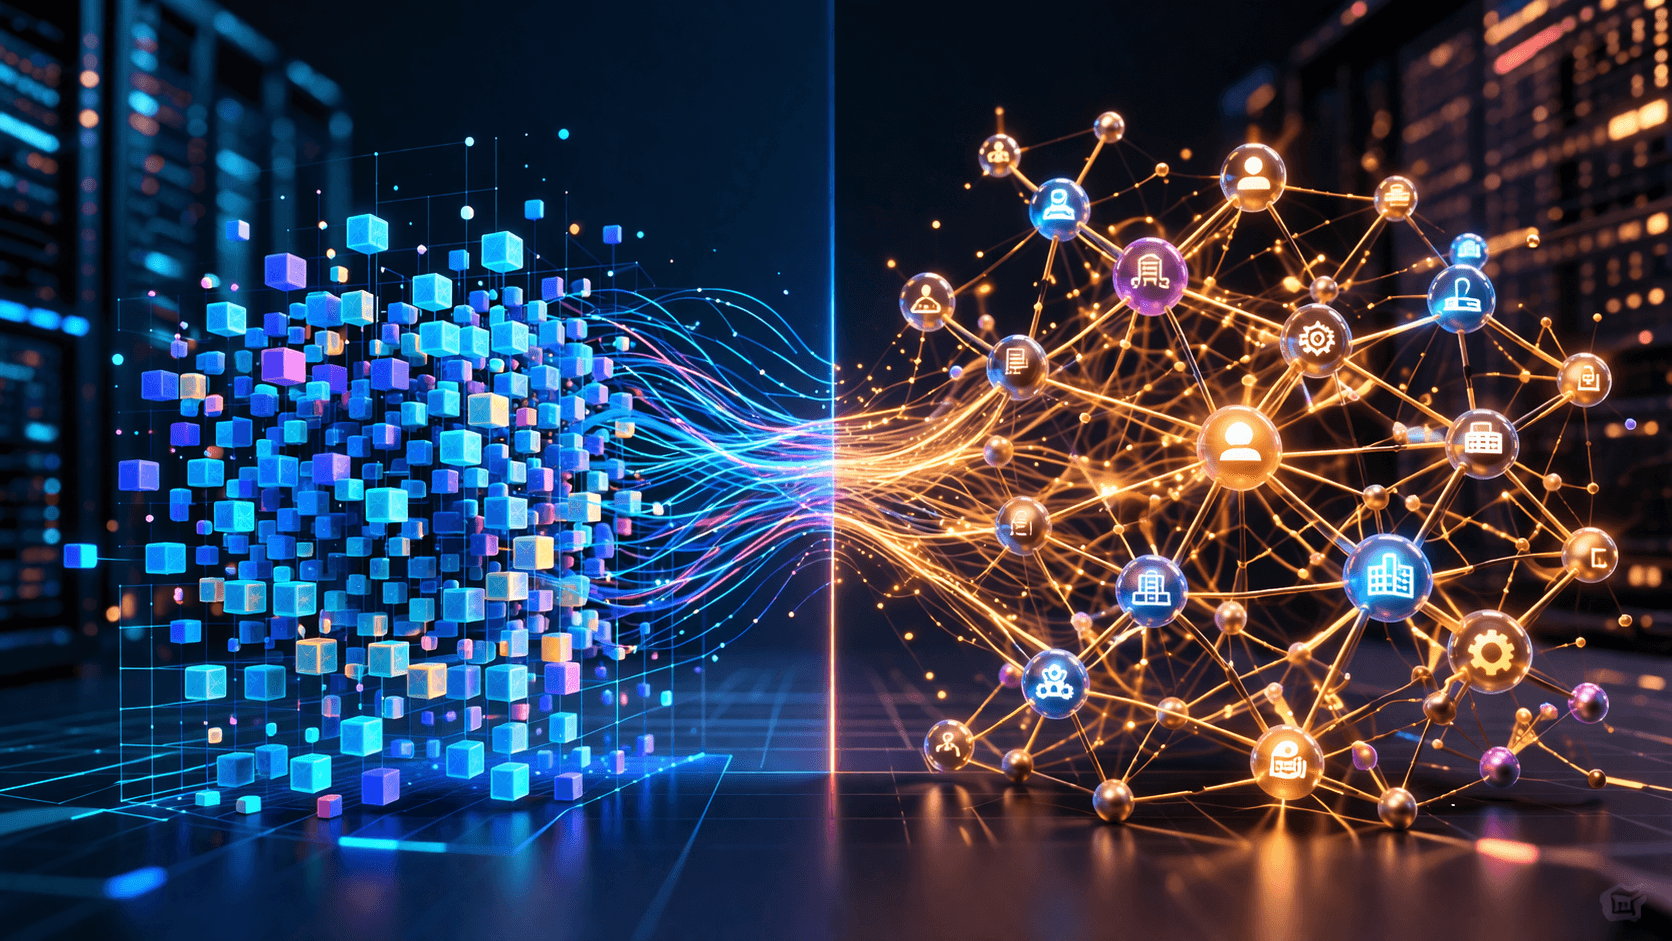
Vector RAG retrieves information by finding text that is semantically similar to a query, using embeddings and a vector database. GraphRAG adds a layer of structured entities and relationships, extracted from your documents into a knowledge graph, so retrieval can follow connections between people, contracts, products, or events. Neither approach is universally better: Vector RAG is usually simpler and faster to deploy for straightforward semantic search, while GraphRAG earns its added complexity when questions depend on multi-hop reasoning or relationships that span many documents. Many enterprise teams end up using both.

GraphRAG Vs VectorRAG Unlocking Enterprise Insights

Key Takeaways

  • Vector RAG is generally the simpler, faster path to production: chunk, embed, index, retrieve.
  • GraphRAG adds structured entity and relationship extraction, which helps with questions that require connecting facts across documents.
  • GraphRAG's advantage shows up most clearly on multi-hop and relationship-heavy questions — not on simple document lookup.
  • Vector RAG remains strong for direct semantic search: policy lookups, contract Q&A, FAQ-style retrieval.
  • GraphRAG introduces real operational overhead: entity extraction quality, ontology decisions, graph maintenance, and additional infrastructure.
  • Hybrid retrieval — using vector search for recall and graph traversal for relationship context — is an increasingly common pattern, not a universal default.
  • The right choice depends on your actual query patterns and evaluation results, not on which architecture is trending.

What Is RAG?

Retrieval-Augmented Generation (RAG) pairs a retrieval step with an LLM's generation step: instead of relying only on what a model learned during training, the system retrieves relevant context from your own data and passes it to the model as part of the prompt. The quality of a RAG system is largely determined by the quality of retrieval — if the wrong information gets pulled in, the model will generate a confident, well-written, and wrong answer. That's why the choice of retrieval architecture, not just the choice of LLM, is one of the more consequential decisions in an enterprise RAG deployment. Vector RAG and GraphRAG are two different answers to the same underlying question: how should the system decide what context is relevant?

What Is Vector RAG?

Vector RAG (sometimes just called "RAG") is the standard retrieval pattern most production systems use today. The pipeline looks like this:

Documents → chunking → embeddings → vector database/index → similarity search → retrieved context → LLM response

Documents are split into smaller chunks, each chunk is converted into a numerical vector (an embedding) that represents its meaning, and those vectors are stored in a vector database. When a user asks a question, the query itself is embedded, and the system finds the chunks whose vectors are closest to it — a proxy for "semantically similar." Those chunks are handed to the LLM as context.

This works well for direct, single-document, semantic retrieval questions, such as:

  • "What does our employee leave policy say?"
  • "What does this contract say about termination?"
  • "What are the password requirements in our security policy?"
  • "Summarize the customer refund policy."

These are fundamentally retrieval problems: the answer lives in a specific, identifiable stretch of text, and finding text that means something similar to the question is enough to surface it.

Vector RAG becomes less naturally suited to questions that require:

  • multi-hop reasoning (answering requires following a chain of facts, not just retrieving one)
  • relationship-heavy questions (the answer depends on how entities connect, not just what a single passage says)
  • cross-document reasoning, where relevant evidence is scattered across many sources
  • corpus-wide synthesis, where no single chunk contains the full answer

To be clear, this doesn't mean Vector RAG cannot answer these questions. Teams routinely extend it with techniques like query decomposition, metadata filtering, reranking, or multi-step retrieval to compensate. But these are workarounds layered on top of an architecture whose native strength is semantic similarity, not structural relationships — and each added technique brings its own tuning and maintenance burden.

What Is GraphRAG?

GraphRAG changes the underlying data structure. Instead of (or alongside) chunk embeddings, it builds a knowledge graph from your documents:

Documents → entity extraction → relationship extraction → knowledge graph → graph/community retrieval → relevant context → LLM

An LLM or extraction pipeline identifies entities (people, organizations, contracts, products, regulations) and the relationships between them (supplies, owns, is governed by, terminates, reports to). These become nodes and edges in a graph. Some GraphRAG implementations also group related entities into communities and generate summaries of those communities to support broader, corpus-level questions. Retrieval then works by traversing the graph — following edges outward from relevant entities — rather than purely by similarity search, and the resulting context is typically linked back to source passages for provenance.

This reframes the retrieval problem. Instead of asking "what text is semantically similar to my query?", the system asks "what entities and relationships are relevant to this question, and how are they connected?" That reframing is what gives GraphRAG an edge on multi-hop and relationship-dense questions — but it's worth noting that GraphRAG isn't a single, standardized technique. Implementations vary considerably in how they extract entities, structure the graph, and retrieve from it, so results can vary by implementation and domain.

GraphRAG vs Vector RAG: Side-by-Side Comparison

GraphRAG vs Vector RAG: Side-by-Side Comparison
DimensionVector RAGGraphRAG
Retrieval mechanismSemantic similarity search over embeddingsGraph traversal over entities and relationships, often combined with community summaries
Data representationChunked text as vectorsKnowledge graph of entities, edges, and source links
Semantic searchCore strengthPresent in some implementations, but not the primary mechanism
Relationship awarenessLimited; relationships must be inferred from co-occurring textExplicit; relationships are modeled directly
Multi-hop questionsRequires added techniques (decomposition, reranking, iterative retrieval)Native strength — graph traversal follows multi-step connections
Single-hop questionsStrong, direct fitWorks, but often more architecture than the question needs
Cross-document reasoningPossible with metadata and orchestration, but not nativeBetter suited, since relationships already span documents
Corpus-level questionsWeaker without additional summarization layersBetter suited when community/summary structures exist
Explainability/provenanceRetrieved chunks are traceable to source textRetrieved relationships can be traced to source text, plus the graph itself offers a structural explanation
Indexing complexityLow to moderateHigher — requires extraction pipelines and schema/ontology decisions
Initial implementation effortLower; established tooling and patternsHigher; more moving parts to design and validate
Update complexityRe-embed and re-index changed documentsRe-run extraction and update graph structure, which is more involved
Query latency considerationsDepends on index size and vector database; generally well-understoodDepends on graph size and traversal depth; can be less predictable without tuning
Infrastructure complexityVector database plus embedding pipelineVector database and/or graph database, extraction pipeline, and orchestration
Cost considerationsPrimarily embedding and storage costsAdds extraction (often LLM-based), graph storage, and ongoing maintenance costs
Best use casesPolicy/document Q&A, FAQs, straightforward knowledge basesSupply-chain analysis, compliance mapping, fraud investigation, complex enterprise knowledge
Main limitationsWeaker on relationship and multi-hop questions without extra toolingExtraction quality, ontology design, and maintenance overhead

We haven't included specific latency, cost, or accuracy percentages here, because those figures vary significantly by dataset, implementation, and workload — any benchmark you see quoted should specify exactly what was tested before you rely on it.

GraphRAG vs Vector RAG: What Questions Does Each Handle Best?

The clearest way to see the difference is through examples.

Vector RAG example: "What does our supplier contract say about termination?" This is a direct lookup — the answer sits in a specific contract clause. Semantic search can find the relevant passage efficiently, without needing to understand how that supplier relates to anything else.

GraphRAG example: "Which suppliers are connected to contracts affected by this regulatory change?" Answering this requires following a chain: regulation → the contract clauses it affects → the contracts containing those clauses → the suppliers tied to those contracts. That's a relationship traversal, not a single semantic match — the kind of question GraphRAG's graph structure is built to handle.

Hybrid example: "Which suppliers are affected by the new regulation, which contracts are involved, and what do those contracts say about termination?" This question has both a relational component (which suppliers and contracts are connected to the regulation) and a semantic component (what the termination clauses actually say). A hybrid approach can use graph traversal to identify the relevant suppliers and contracts, then use vector search to retrieve and summarize the specific clause language within those documents — combining relationship-aware narrowing with semantic precision.

When Should You Use Vector RAG?

Vector RAG is often the better choice when:

  • Questions are primarily semantic lookups against a defined set of documents
  • You're building internal knowledge bases, FAQ systems, or document Q&A tools
  • Content covers policies, procedures, contracts, or support documentation
  • Your underlying content changes frequently and needs to stay easy to re-index
  • Deployment speed and operational simplicity matter more than handling complex relationship queries
  • Relationships between entities aren't central to how users actually ask questions

None of this makes Vector RAG a lesser architecture — for a large share of enterprise RAG use cases, it's the right tool, and adding graph infrastructure would be unnecessary overhead.

When Should You Use GraphRAG?

GraphRAG's added complexity is more likely to be justified when:

  • Questions routinely require multi-hop reasoning across entities
  • Your domain is inherently relationship-heavy: supply chains, corporate ownership structures, financial networks
  • You're supporting fraud investigation or anomaly detection, where connections between entities are the signal
  • Compliance and regulatory mapping require tracing how a rule, product, or vendor connects across the business
  • Legal or scientific research workflows depend on synthesizing evidence across many documents
  • Analysts currently manually stitch together information from multiple sources to answer a single question

If your team can point to real recurring questions that fit this pattern, GraphRAG is worth evaluating seriously. If those questions are rare, the extraction and maintenance overhead may not pay for itself.

When Should You Use Hybrid RAG?

Hybrid retrieval combines vector search and graph retrieval rather than forcing a single choice. Vector search provides broad semantic recall; graph retrieval adds relationship-aware context where it's needed. In practice, this doesn't mean running both systems on every query — a routing or orchestration layer can classify incoming questions and decide whether graph traversal is warranted, falling back to vector search (or using both) as appropriate.

This pattern is becoming more common as teams recognize that most enterprise question sets are mixed: some queries are simple lookups, others are genuinely relational. But hybrid retrieval isn't automatically the right answer for every organization — it adds its own orchestration and evaluation complexity, and it only pays off if you actually have a meaningful volume of both query types.

GraphRAG vs Vector RAG: Cost and Complexity

Vector RAG has a comparatively simple pipeline: chunk, embed, index, retrieve. Each step is well-understood, and there's a mature ecosystem of tooling around it.

GraphRAG's pipeline has more stages, each of which introduces its own cost and failure modes:

  • Entity extraction (often LLM-based, which adds inference cost)
  • Relationship extraction and validation
  • Graph construction and schema/ontology design
  • Ongoing graph updates as source documents change
  • Community detection and summarization, in implementations that use it
  • Additional infrastructure for graph storage and traversal
  • Additional monitoring to catch extraction drift or graph quality issues over time

We won't cite a universal cost multiplier here — claims like "GraphRAG costs 3x" or "10x" more than Vector RAG depend entirely on the specific implementation, document volume, and workload, and should be treated skeptically unless tied to a named benchmark with clear methodology. The more useful question for your organization is: does the retrieval improvement on your actual queries justify the additional engineering and operating cost? That's answerable through evaluation on your own data, not through generic industry claims.

GraphRAG Limitations

The case for GraphRAG is real, but it comes with trade-offs that are easy to underweight.

Higher implementation complexity. Building a working graph pipeline requires more design decisions and more moving infrastructure than standing up a vector index.

Entity and relationship extraction quality. GraphRAG is only as good as its extraction step. Incorrect or missed entity and relationship extraction propagates directly into incorrect graph structure — and, downstream, into wrong or misleading answers that can look structurally well-supported even when they aren't.

Ontology and schema challenges. Different domains need different graph structures. A schema designed for supply-chain relationships won't necessarily generalize to legal or financial relationships, and getting this wrong early can require significant rework later.

Maintenance overhead. Source documents change. Every update requires re-running extraction, validating new relationships, and keeping the graph consistent — a heavier and more error-prone process than re-embedding a changed document. Without active maintenance, a knowledge graph can drift out of sync with the underlying source of truth faster than a vector index does.

For balance: Vector RAG's own limitation is the mirror image of this — it can miss relationship-dependent answers not because the information isn't retrievable, but because similarity search alone doesn't model connections. That gap is addressable with added techniques, but it's a real limitation worth naming rather than glossing over.

How to Evaluate GraphRAG vs Vector RAG for Your Organization

Rather than choosing an architecture based on which one is generating more buzz, a more defensible process looks like this:

  1. Audit real query patterns. Pull actual or representative questions your users ask (or would ask) of the system. Tag them as single-hop/semantic or multi-hop/relational.
  2. Estimate the mix. If the large majority are semantic lookups, Vector RAG alone may be sufficient. If a meaningful share are relational, GraphRAG or hybrid retrieval deserves a pilot.
  3. Pilot on a narrow, representative dataset, not your entire corpus. This surfaces extraction quality issues early, before they're expensive to fix.
  4. Evaluate against your own queries, using retrieval precision/recall and end-to-end answer quality — not generic public benchmarks, which may not reflect your domain.
  5. Weigh ongoing maintenance capacity, not just build cost. A graph that isn't maintained degrades in ways that are harder to detect than a stale vector index.
  6. Reassess periodically. Query patterns shift as an organization's use of the system matures; the right architecture today may not be the right one in a year.

Where Data Privacy and Security Fit Into the Decision

Architecture choice isn't just about retrieval accuracy — for regulated or security-conscious organizations, it also touches how sensitive data is extracted, stored, and accessed. GraphRAG in particular introduces new surfaces to think about: entity extraction pipelines that process raw documents, a graph structure that may make relationships between sensitive entities more explicit and more queryable than they were in unstructured text, and additional infrastructure that needs its own access controls and audit trails.

This is where Questa AI's approach is built to be a meaningful differentiator rather than a marketing claim: enterprise deployments — whether Vector RAG, GraphRAG, or hybrid — are designed with data governance as a first-class requirement, including control over what gets extracted into a graph, how relationships involving sensitive entities are access-controlled, and how retrieval activity is logged for audit purposes. The architectural decision (Vector RAG vs. GraphRAG vs. hybrid) should be made on retrieval fit first; privacy and security controls should then be applied consistently regardless of which architecture you land on.
Frequently Asked Questions

Not universally. GraphRAG tends to outperform on multi-hop and relationship-heavy questions; Vector RAG tends to be simpler, faster to deploy, and sufficient for direct semantic lookups. The better choice depends on your query patterns.

Yes — "Vector RAG" and "traditional RAG" generally refer to the same embedding-and-vector-search pattern. "GraphRAG" is the term used for the knowledge-graph-based variant.

Yes. Hybrid retrieval architectures use vector search for semantic recall and graph traversal for relationship-aware context, often with a routing layer deciding which to use per query.

No. Many GraphRAG implementations still use vector search as part of their retrieval process — for example, to find entry points into the graph or to retrieve source text linked to graph nodes.

Underestimating the ongoing cost of entity extraction quality and graph maintenance. A graph that isn't kept in sync with source documents can produce confidently wrong answers.

Look at your actual or anticipated query patterns. If a meaningful share require connecting facts across multiple documents or entities, GraphRAG or a hybrid approach is worth piloting. If most questions are direct lookups, Vector RAG alone is often enough.

Conclusion

Vector RAG and GraphRAG aren't competing answers to the same problem — they're built for different shapes of questions. Vector RAG remains the simpler, faster path for direct semantic retrieval, and it's still the right choice for a large share of enterprise use cases. GraphRAG earns its added complexity when your users are regularly asking questions that require connecting entities and relationships across documents, not just finding a similar passage.

For many organizations, the real answer isn't "pick one" — it's a hybrid architecture that routes semantic and relational queries to the retrieval method suited to each. The most reliable way to decide is to look at your own query patterns and run a focused evaluation, rather than defaulting to whichever architecture is generating the most attention. And whichever path you choose, the privacy and access controls around that data should be treated as a first-class requirement from the start, not an afterthought bolted on later.

Abhi Author

About the author:

Abhiroop Sharma

Ex. Distinguished technology leader

Distinguished technology leader with 18+ years of progressive experience spanning AI, Web3, SaaS, eCommerce, and blockchain governance. Demonstrated success in driving digital transformation across global markets, with expertise in scaling enterprise solutions from concept to implementation. Proven track record of reducing implementation timelines by 50% and building high-performing teams across multiple organizations. Currently focused on pioneering AI implementation and Web3 integration strategies for emerging technology ventures.
Follow the expert:

Related Articles

View More
AI Chats and Legal Privilege: What Enterprises Must Know
JUN 08, 2026
Privacy Cafe

AI Chats and Legal Privilege: What Enterprises Must Know

Does using AI waive attorney-client privilege? A clear guide to AI chat confidentiality, discoverability, retention, and enterprise legal governance today.

Read More
AI Risks in Financial Services: 2026 Guide for Banks
APR 27, 2026
Privacy Cafe

AI Risks in Financial Services: 2026 Guide for Banks

A 2026 guide to AI risks in financial services — cybersecurity, data privacy, model, regulatory, fraud and systemic risk — with a practical framework for banks.

Read More
AI Security Riders Explained: 2026 Cyber Insurance Guide
MAR 19, 2026
Privacy Cafe

AI Security Riders Explained: 2026 Cyber Insurance Guide

AI security riders are reshaping cyber insurance in 2026. See how shadow AI, redaction, and underwriting visibility shape what your policy actually covers.

Read More